

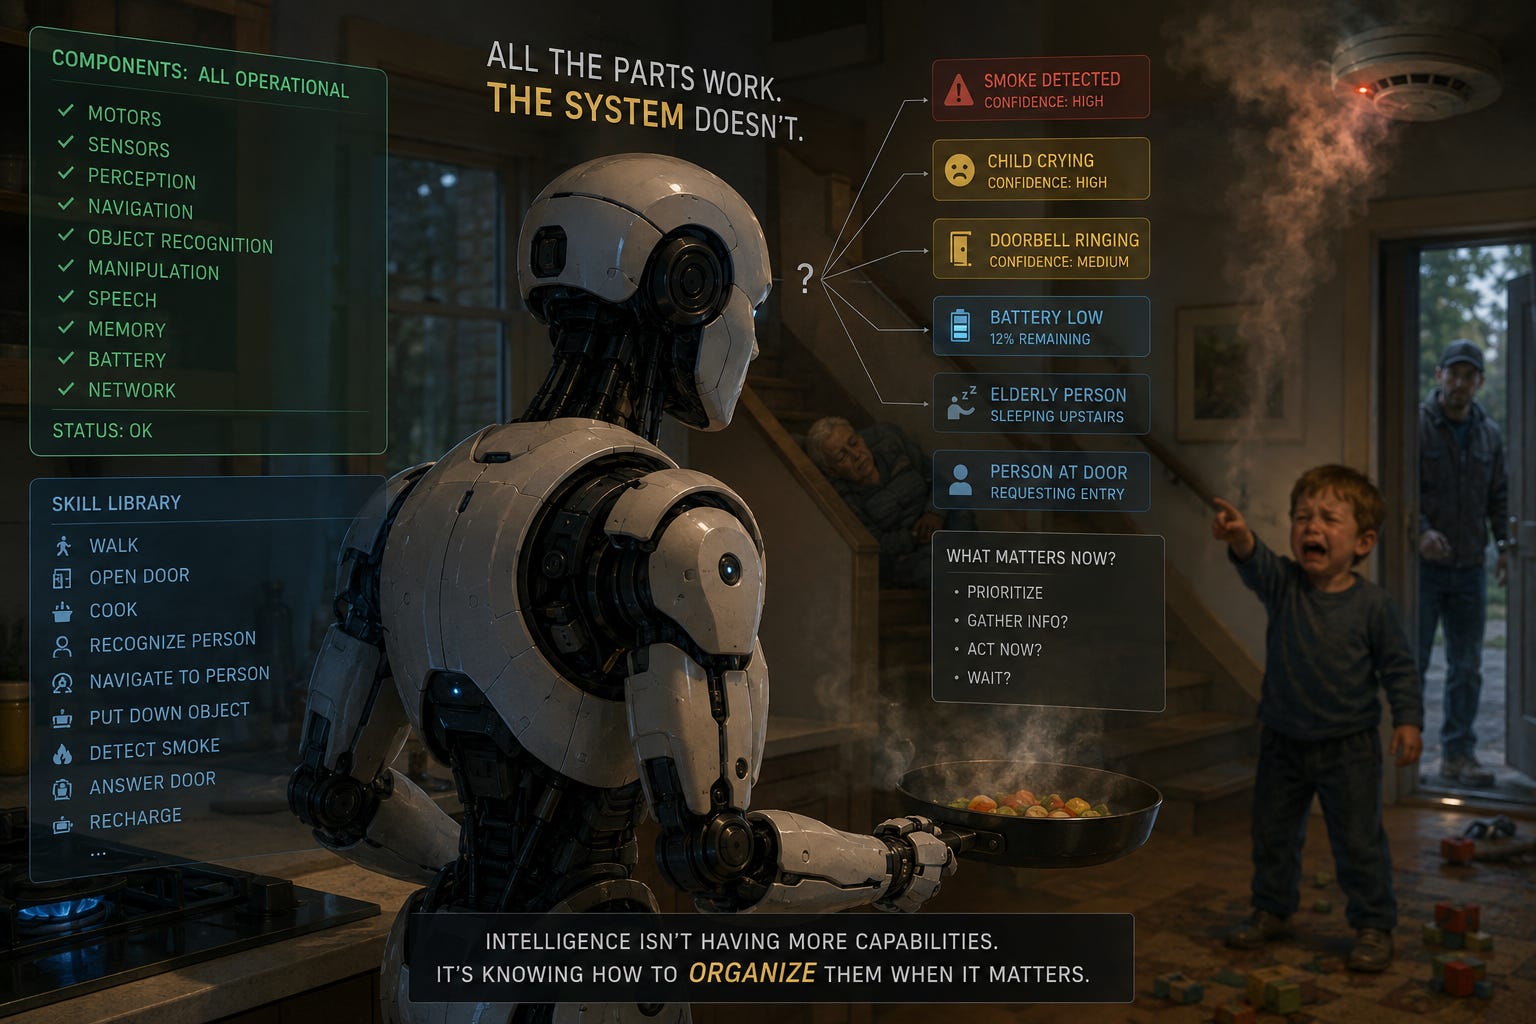
Why building intelligent robots may be less about adding capabilities and more about learning how to organize them
There is a sentence every systems architect eventually learns to distrust:
“All the components are working.”
It usually appears five minutes before someone explains that the system itself is not.
The database is healthy. The APIs respond. Authentication works. Every microservice passes its tests. The network is available. The individual teams have checked their dashboards. And yet the customer cannot complete a transaction. Nothing is necessarily broken in isolation. The failure lives somewhere between the parts.
After years working with complex systems, this has become almost instinctive: a collection of functioning components is not the same thing as a functioning system.
A recent robotics paper made me realize we may be approaching artificial intelligence with a surprisingly similar blind spot.
Teach and Grow, by Chang Nie, Zhe Liu and Hesheng Wang, proposes an appealing solution to lifelong robot learning. Instead of retraining an entire foundation model every time a robot encounters something new, the system acquires explicit, reusable Skill Blocks. A new capability can be demonstrated, verified, stored and reused while the underlying model remains untouched.
There is a lot to like about this idea. It also exposes a much harder question: what happens when we finally have all the skills?
The retraining tax
Modern robotics still inherits an awkward assumption from machine learning: when a system cannot do something, learning usually means changing the model. Collect more examples, fine-tune, retrain, update weights, validate again.
For software operating in purely digital environments this is already expensive. For robots it becomes substantially worse, because physical experience is costly to generate. Teach and Grow calls this the retraining tax and offers modular growth as the alternative.
Instead of forcing every new competence back into the parameters of a large model, the system constructs reusable Skill Blocks. Each block describes a meaningful capability, the conditions under which it should apply, how the current situation should be grounded, which executor can perform the behavior, how success is verified, and what recovery actions are allowed.
The distinction matters. The robot is not simply memorizing a trajectory. It is trying to preserve something closer to: Under these circumstances, I know how to produce this effect.
Successful capabilities enter a Skill Library. Experiences—including failures and repairs—can remain in a separate memory. The architecture therefore separates knowing what happened from knowing what to do.
That is a sensible idea. It is also very familiar to anyone who has designed large software systems. Do not rebuild everything when one capability changes. Isolate responsibilities. Preserve stable interfaces. Allow components to evolve independently.
In engineering terms, it is difficult to argue against that instinct. And yet modularity only solves part of the problem.
Imagine that it works perfectly
Let us grant the strongest possible version of the argument. Suppose the robot eventually possesses thousands of reliable capabilities. It can walk, open doors, recognize people, manipulate unfamiliar objects, navigate buildings, prepare food, answer questions, recharge itself, use tools, remember previous interactions, ask for assistance, detect obstacles, recover from failed grasps, and communicate fluently.
Every individual capability has been tested. Every module works.
Have we built an intelligent organism?
Not necessarily. We may simply have built an extraordinary collection of capabilities. Because now another problem appears: who decides what matters?
The problem begins when everything happens at once
Imagine a domestic robot preparing dinner. It is carrying a hot pan. A child begins crying in another room. The smoke detector reports an abnormal reading. Someone rings the doorbell. The robot remembers that an elderly person is sleeping upstairs. Its battery has fallen to 12%. At the same time, someone outside asks: “Can you open the door?”
There is no obvious SkillBlock(resolve_everything).
Every individual subsystem may be functioning perfectly. The robot can identify the crying, recognize smoke, put down the pan, open the door, navigate toward the child, and recharge. The problem is no longer capability. The problem is organization.
What deserves attention first? Which action can be interrupted? Which observation is uncertain but potentially catastrophic? Which task can wait? What information should be gathered before acting? When is the cost of waiting greater than the cost of acting with incomplete information? Does the person at the door matter at all? Should the robot abandon dinner, wake the sleeping person, or investigate the smoke before approaching the child?
There may be no complete information available. There usually isn’t.
More importantly, the same observation does not always demand the same response. A low battery means something different beside a charger than halfway through an outdoor task. A strange sound means something different after it has already been heard twice. Smoke means something different depending on where it appears, what the agent is doing, who else is present, and what other evidence is available.
The meaning of a signal therefore depends partly on the state of the system encountering it: what it is doing, what it remembers, what it needs, what it expects, and what it believes might happen next. The same observation can produce different actions without either response being inherently wrong.
And this is where the problem starts looking much less like tool selection and much more like intelligence.
Intelligence under incomplete information
We sometimes describe intelligent decision-making as though the ideal agent gathers enough information, constructs an accurate model, and then chooses the optimal action. Real life rarely provides that luxury.
We decide with fragments. Something happened before. Something resembles another situation. One observation contradicts another. There is not enough time to investigate everything. Some consequences are reversible; others are not. Experience tells us that one signal is probably irrelevant while another deserves immediate attention. Logic eliminates some possibilities. Memory suggests others. And eventually we act—not because we finally know everything, but because waiting for complete information is itself a decision.
This becomes painfully obvious in complex systems. An architect almost never has every variable available when an important decision must be made. You work with incomplete requirements, historical incidents, technical constraints, organizational pressures, partial measurements, competing priorities, and a deadline.
Experience matters precisely because the available evidence is incomplete. You recognize patterns, but more importantly, experience gradually teaches you what might matter. You learn which questions are worth asking, which uncertainty can be tolerated, which uncertainty cannot, and which apparently minor signal deserves another look.
And occasionally you are wrong.
Intelligence does not eliminate uncertainty. It organizes action despite it.
That is different from planning
It would be tempting to call this simply a planning problem. I don’t think that captures it.
A planner generally begins after something has already established: this is the objective. But in an open environment, determining the objective can itself be part of the problem.
The robot preparing dinner had an objective. Then the child cried. Then smoke appeared. The world did not politely wait for the current plan to finish. Something must decide whether the previous objective is still relevant. That requires more than selecting the next action in a sequence. It requires continuously reorganizing what matters.
There is a difference between “How do I accomplish this goal?” and “What should my goal be now?” The second question is much harder.
The strongest counterargument
This is where another line of robotics research provides an important objection. Physical Intelligence’s π0.5 takes a very different approach from explicit Skill Blocks. Rather than accumulating a library of separately represented competencies, it trains a vision-language-action model across heterogeneous sources of experience. The goal is to build a sufficiently general policy that can interpret language, perceive novel environments, and generate actions directly.
The results are impressive. The system performs long-horizon manipulation tasks in homes it never encountered during training. It can clean kitchens and bedrooms, manipulate novel objects, and use semantic knowledge acquired through heterogeneous training to generalize beyond individual demonstrations.
That matters, because it shows that integration does not necessarily require manually assembling thousands of independent modules. A sufficiently rich learned policy can absorb many behaviors into a shared representation. Perhaps, then, the modularity problem eventually disappears. Train on enough situations. Expose the system to enough diversity. Allow the model to learn the interactions between perception, language, and action. The orchestration itself may emerge.
That is a serious possibility. But there is an important difference between learning to perform long-horizon tasks and maintaining coherent organization in an indefinitely changing world.
Long horizon is not open horizon
Cleaning a kitchen can require dozens or hundreds of actions. That is difficult. But the task still has semantic boundaries. There is a kitchen. There is a notion of cleaning. There are objects whose relationships can be evaluated. Eventually the task ends.
An organism does not receive that convenience. Its horizon is open. There is no episode complete. While pursuing one objective, another can appear. Its own internal condition changes. The environment changes. Other agents interfere. Previously irrelevant information becomes important. Something learned yesterday changes the interpretation of what happens today. And there is no guarantee that the task that mattered thirty seconds ago is still the most important task now.
This creates a different architectural problem. Not “Can the system execute a complicated sequence?” but “Can the system remain coherently organized while the definition of what matters keeps changing?”
That distinction may prove fundamental.
Architecture has seen this movie before
There is an old temptation in systems engineering. If every business capability has its own service, every service exposes a clean API, every API follows the contract, and every component can scale on its own, then surely the whole system will work.
Of course, it doesn’t.
Distributed systems produce problems that don’t belong to any single piece. Latency piles up. Failures cascade. Retries create traffic storms. State drifts out of sync. Dependencies create unexpected bottlenecks. Two decisions that each make perfect sense on their own can combine into a global disaster.
The architecture matters precisely because local correctness does not guarantee global correctness. I suspect artificial agents face an even harder version of this problem.
Having more competent capabilities is useful. But intelligence may depend less on the number of things an agent can do, and more on how those things continuously shape one another. What the agent perceives changes what it remembers. What it remembers changes what it considers important. What it considers important changes where it looks next. Where it looks changes what it perceives. Its actions alter the world, the changed world produces new evidence, and the consequences of those actions become part of the history from which future decisions are made.
There is therefore a state that belongs not to any single capability, but to the agent as a whole. That state is continuously rewritten by the encounter between the agent and its environment.
That is not a pipeline. It is a loop.
Learning should change more than the list of available tools
This is where Teach and Grow becomes particularly interesting. Suppose the robot learns a new Skill Block. Before learning it, a particular object was irrelevant because the robot could not do anything useful with it. After learning the skill, the same object becomes an opportunity.
Nothing changed in the external world. But something changed in the world available to the agent. That means genuine learning should potentially modify more than the list of executable skills. It may change attention, perception, planning, what memories become relevant, which situations appear dangerous, and what the agent considers possible.
A child who learns to read does not simply acquire a new callable function called READ(). The environment itself begins to contain information that previously did not exist for that child. Street signs change. Packages change. Screens change. Books change. The physical objects were always there. Their operational meaning was not.
That is a much stronger form of integration.
Perhaps intelligence begins with continuous constraint resolution
There may be another way to frame the problem. At any moment, an embodied agent exists inside multiple simultaneous constraints: limited energy, limited time, limited sensing, a body occupying one place, previous commitments, current objectives, potential threats, incomplete knowledge, other agents, physical limits, and memories of what happened before.
The next action must somehow emerge from all of these.
This is why prioritization, urgency, and experience are so difficult to isolate as independent “skills.” Urgency is relational. Smoke is irrelevant in some contexts and existential in others. Low battery can be unimportant at 30% while sitting beside a charger and extremely important at 30% while halfway through an outdoor task. A sound may be ignored once and investigated after being repeated. The meaning of a signal depends on the state of the system encountering it.
So perhaps part of what we call intelligence begins here: in continuously finding a workable organization among competing constraints without expecting that organization to remain valid for very long. That sounds less like calling the correct tool and more like continuously solving a changing constraint problem.
And importantly, the solution is never final. The next observation changes it again.
Experience is not simply memory
This also exposes another distinction. We often give agents memory and assume that experience will follow. But storing previous events is not the same as having experience.
Experience means that previous events change the interpretation of current ones. If I have seen a particular architecture fail repeatedly under load, I may react differently to a design that resembles it. The database containing those incidents is memory. The changed judgment is experience.
For an artificial agent, that distinction matters enormously. A robot may store every failure it has ever experienced. But unless those failures change attention, confidence, prioritization, or future behavior in relevant situations, the robot has an archive. Not experience.
A useful memory system should therefore be judged not only by what it can retrieve, but by whether what it retrieves changes future behavior when it matters. That may be one of the missing connections between lifelong-learning systems and genuinely integrated agents.
What would actually convince me?
Not a robot with more skills. Not another impressive long-horizon demonstration.
I would want to see something much simpler and, in some ways, harder. Give an agent several simultaneous pressures. Do not tell it which one is the task. Do not even guarantee that the original task remains the most important one. Give it incomplete observations. Allow some uncertainties to be investigated, but make investigation costly. Introduce something unexpected halfway through. Then observe whether previous experience changes what the agent considers relevant. Afterward, change the environment again.
The interesting metric would not simply be task success. We would want to know whether it noticed the right thing, whether it changed priorities appropriately, whether it gathered information when uncertainty mattered and ignored uncertainty when resolving it would achieve nothing. We would want to know whether previous experience altered the decision and whether the agent could recover when its initial interpretation proved wrong.
And perhaps most importantly: did the agent maintain coherent behavior when there was no single correct script to follow?
That would begin to test integration rather than capability accumulation.
What result would change my mind?
There is a perfectly reasonable possibility that sufficiently general learned policies will solve much of this. If systems descended from architectures like π0.5 begin to demonstrate robust reprioritization across genuinely novel, conflicting, and open-ended situations—without explicit orchestration machinery—then the argument for a distinct integration architecture becomes weaker. Perhaps orchestration really can emerge from scale, diverse experience, and sufficiently powerful recurrent state.
Likewise, if modular systems such as Teach and Grow demonstrate that a growing collection of skills naturally produces adaptive prioritization once combined with memory and verification, then perhaps the distinction I am drawing is unnecessarily strong.
But those demonstrations must involve more than increasingly difficult predefined tasks. The system must be allowed to encounter situations where the problem itself changes. Otherwise we are still testing increasingly impressive problem solving—not whether the agent can determine what problem it is currently facing.
The pragmatic reading
I think Teach and Grow is pointing in a useful direction. Learning something locally should not necessarily require rewriting everything globally. That is good architecture.
π0.5 demonstrates something equally important: broad shared representations can integrate capabilities in ways that explicit modular systems might struggle to reproduce. That is good learning.
I would not choose between them.
The difficult problem sits above—or perhaps between—the two. We need systems capable of accumulating specialized competence without losing the ability to behave as a coherent whole. They must perceive with incomplete sensors, remember selectively, use previous experience, estimate urgency, resolve competing constraints, change objectives, abandon obsolete plans, gather additional evidence when necessary, and eventually act without ever possessing the complete state of the world.
Because that last condition is not an edge case. It is normality.
We never have all the information on the table. We make decisions using what we can perceive now, what experience tells us might matter, what logic allows us to infer, and what the consequences of waiting might be. Sometimes we gather more evidence. Sometimes there is no time. Sometimes experience points us in the wrong direction. And then the consequences become new experience.
Building each of those capabilities separately is difficult. Making them work together may be the actual problem.
A systems architect would probably describe it in less glamorous terms:
All the services are up.
Now let’s see if the system works.
Reference: Teach and Grow: An Agent-Centered Architecture for General Robot Learning